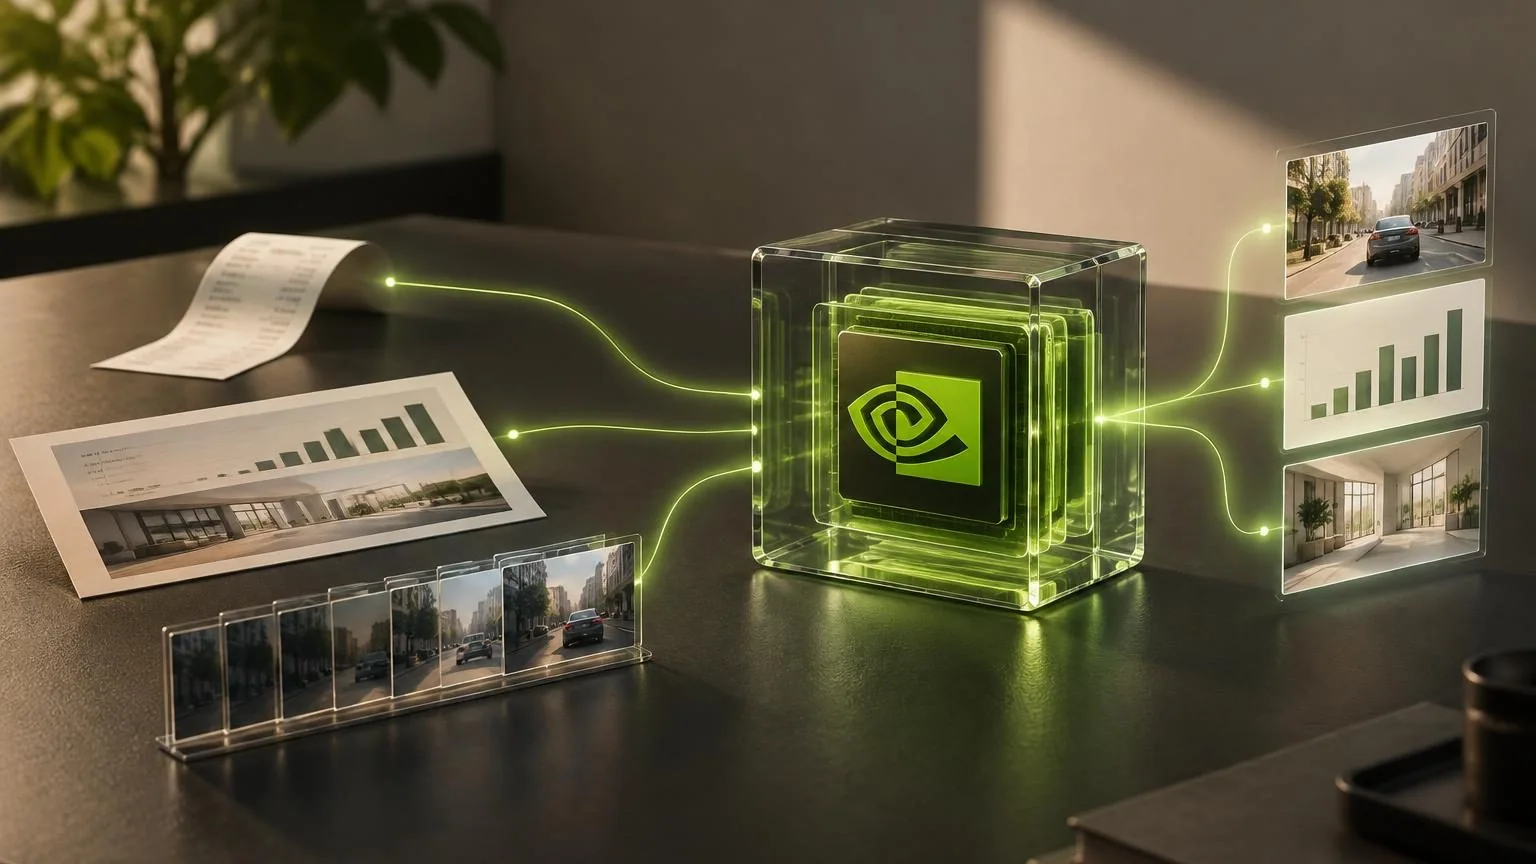
NVIDIA released Nemotron 3.5 Super VL on October 15, 2026, bringing visual understanding and tool use into one open-weight model for specialized agents. Its proposed value is fewer boundaries between reading evidence and acting on it. NVIDIA's announcement describes the release and its intended workflows.
What changed
The model accepts text, images, and video and produces text. NVIDIA lists document interpretation alongside reasoning and tool use. This makes document-heavy operations a relevant place to evaluate it, rather than assuming every chatbot needs a replacement. Source: NVIDIA technical blog.
The architecture has 120 billion total parameters, with 12 billion active per token. That active count describes computation, not the memory required to hold the full model. Source: NVIDIA model card.
Check the deployment recipe, not just the headline
The quantized model card lists configurations including one DGX Spark, one H200, or two H100 GPUs. These are specific supported setups, not a promise that any desktop can run the model effectively. Review the hardware table.
Its stated context ceiling is one million tokens, but NVIDIA notes that actual deployment settings may use less to accommodate memory and concurrency. Capacity on paper is not a production service-level target. Read the context qualification.
A practical pilot
Our recommendation is to choose one reversible job, such as extracting receipt fields into a review queue. Keep payment execution and irreversible changes outside the pilot.
- Freeze the test set. Include difficult scans, unusual layouts, and missing fields.
- Score the whole job. Count correct records, retries, human corrections, and elapsed time.
- Price successful outcomes. Include serving, integration, and review costs rather than comparing token prices alone.
- Test failure behavior. Require an explicit review path when evidence is unclear or tools fail.
The business implication
Our interpretation: the interesting opportunity is a simpler evidence-to-action workflow, not automatic replacement of a frontier model. Advance only if your own test shows an acceptable balance of accuracy, cost, and operational control. Open weights create an evaluation option, not a finished business process.