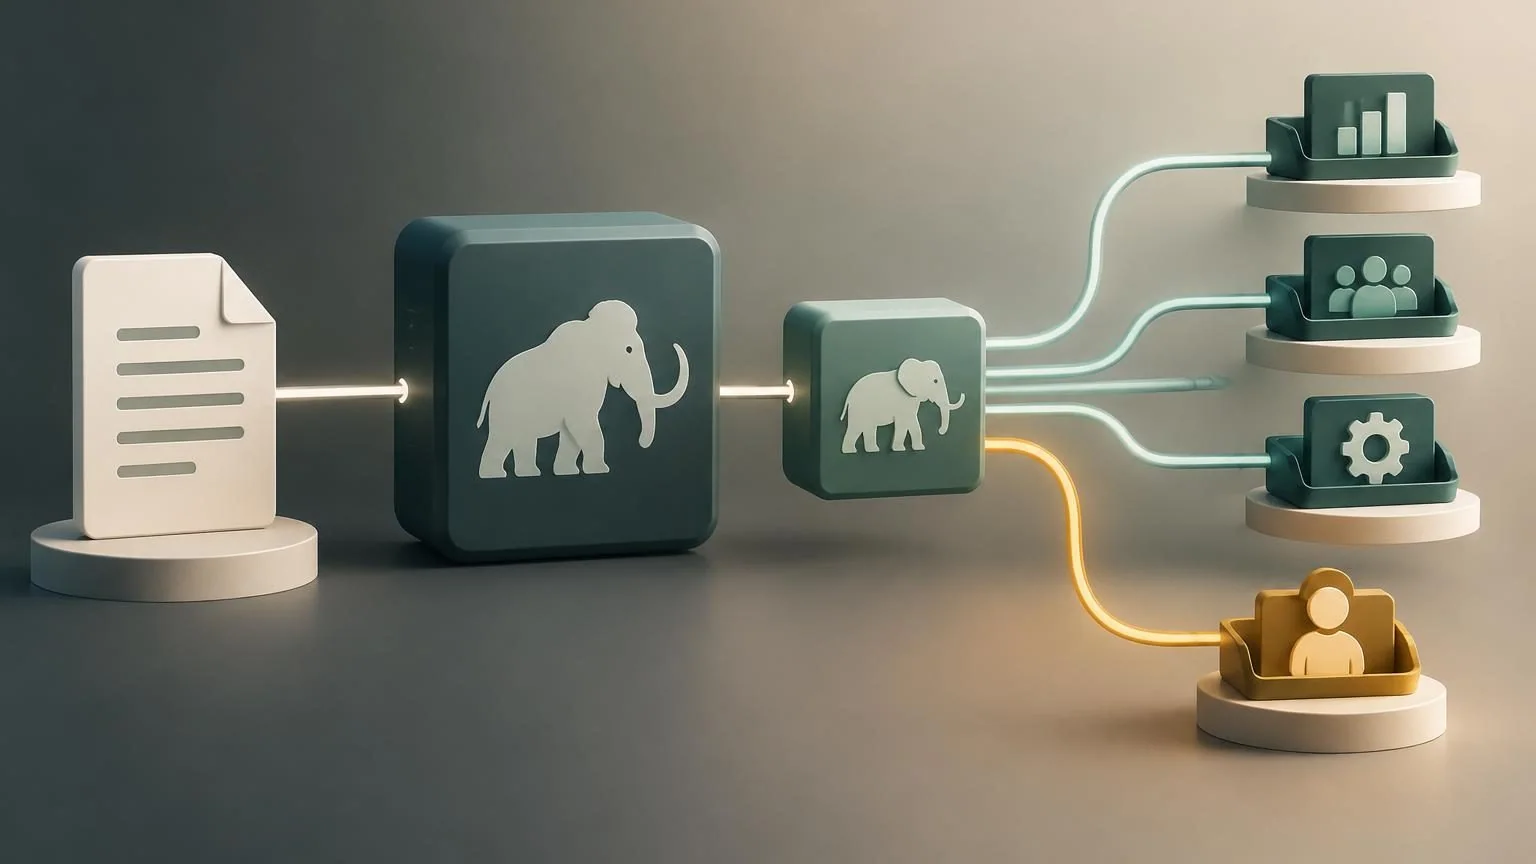
Base Labs, Baseten’s research team, released mammoth-1 and elephant-1 on October 21, 2026. The 27B and 9B decision models return probabilities over predefined answers instead of writing prose. Their intended role is to route, classify, and score work inside larger applications, with both hosted access and downloadable models available.
What shipped, and what is available now
The distinctions between announcement, preview, API access and downloadable weights are important:
- Announcement: Baseten’s dated release post is October 21, 2026. That is the public announcement date used here, not a backdated Nerova publication date.
- Preview: The October 21 announcement describes a release, not a preview-only waitlist. Earlier evaluation access should not be confused with public availability.
- Hosted API: Both current model-library pages list the /v1/systemone endpoint and provide authenticated request examples.
- Downloadable weights: Both Hugging Face repositories list MIT licensing and actual Safetensors weight files, alongside serving code. This is more than an open-weight promise.
These access paths are documented separately in the announcement, Baseten’s library and the repositories.
The model cards specify that the launch free week ended October 27, 2026, at 11:59 p.m. Pacific Time. That deadline has passed as of this November 1 coverage; “free for a week” should not be read as a new trial starting today. Hosted availability and the introductory promotion are different facts.
Why this is a different component in an agent workflow
Base Labs post-trained Qwen3.5-27B and Qwen3.5-9B on 6.21 million decision examples. Its technical report describes block-bidirectional attention in full-attention layers, with a shared input prefix reused across questions. Supported questions include named choices, yes/no checks and ordered scores. Instead of asking a model to write “send this to billing” and parsing that sentence, an application receives probabilities for the supplied alternatives.
Our operational interpretation is that these models fit a bounded decision layer, not the entire agent. In a proposed support workflow, one request could assess department, urgency and whether a refund is being requested. Separate application logic would decide whether to route, escalate or authorize any action. Detecting a refund request must not itself grant permission to issue money.
That separation is the practical opportunity: evaluate a narrow decision without also requiring a customer-facing response. It is not evidence that an autonomous team can safely complete the downstream job.
The benchmark headline needs its original date and scope
At launch, Baseten reported mammoth-1 ranked first among 208 models on Jev Decision Index 0.4, scoring 71.24. It positioned elephant-1 as the leading 9B model. These are launch-era claims about a particular index edition—not a verified statement that either model leads every current leaderboard on November 1.
The Artificial Analysis numbers also require care. Base Labs labels its 65.9 mammoth-1 and 65.2 elephant-1 results as a replication of that index. Separately, its report says it worked with Artificial Analysis before release to benchmark elephant-1, reporting a rounded score of 65. A vendor replication and an externally run evaluation should not be collapsed into one independent result. Neither establishes accuracy on a company’s ticket queue.
Limits that should shape the first business pilot
Both model cards specify a maximum sequence length of 16,384 tokens and say overlength requests are refused rather than truncated. Their documented self-hosting path uses a pinned OneJev runtime with a serving patch and one CUDA GPU; that does not establish that any GPU has sufficient memory. Download access alone is not deployment readiness.
For a proposed routing pilot, our recommendation is to replay labeled historical cases before enabling actions. Include ambiguous ownership, missing information and cases where none of the listed destinations is appropriate. Measure wrong automatic routes and the human-review workload together; a probability threshold is useful only if its behavior holds on that workload.
Finally, test model probabilities and any normalized confidence field separately: Base Labs’ report defines them differently. This article reports no firsthand performance tests. The release creates a concrete evaluation opportunity, not proof of cheaper operations, calibrated confidence in every domain or safe unattended decisions.