OpenAI made its Decisions API generally available with gpt-6-luna on October 22, 2026, following its October 6 public beta. This catch-up report covers the October 22 announcement. The update remains relevant for businesses assessing bounded classification and routing workflows: requests now support 400 questions instead of 200, alongside new input and caching options.
What changed between beta and general availability
The October 22 changelog identifies four headline changes: shared-input prompt caching, images inside individual question instructions, structured evidence through input_json, and the higher question limit. These are additions to the existing API, rather than a newly announced model.
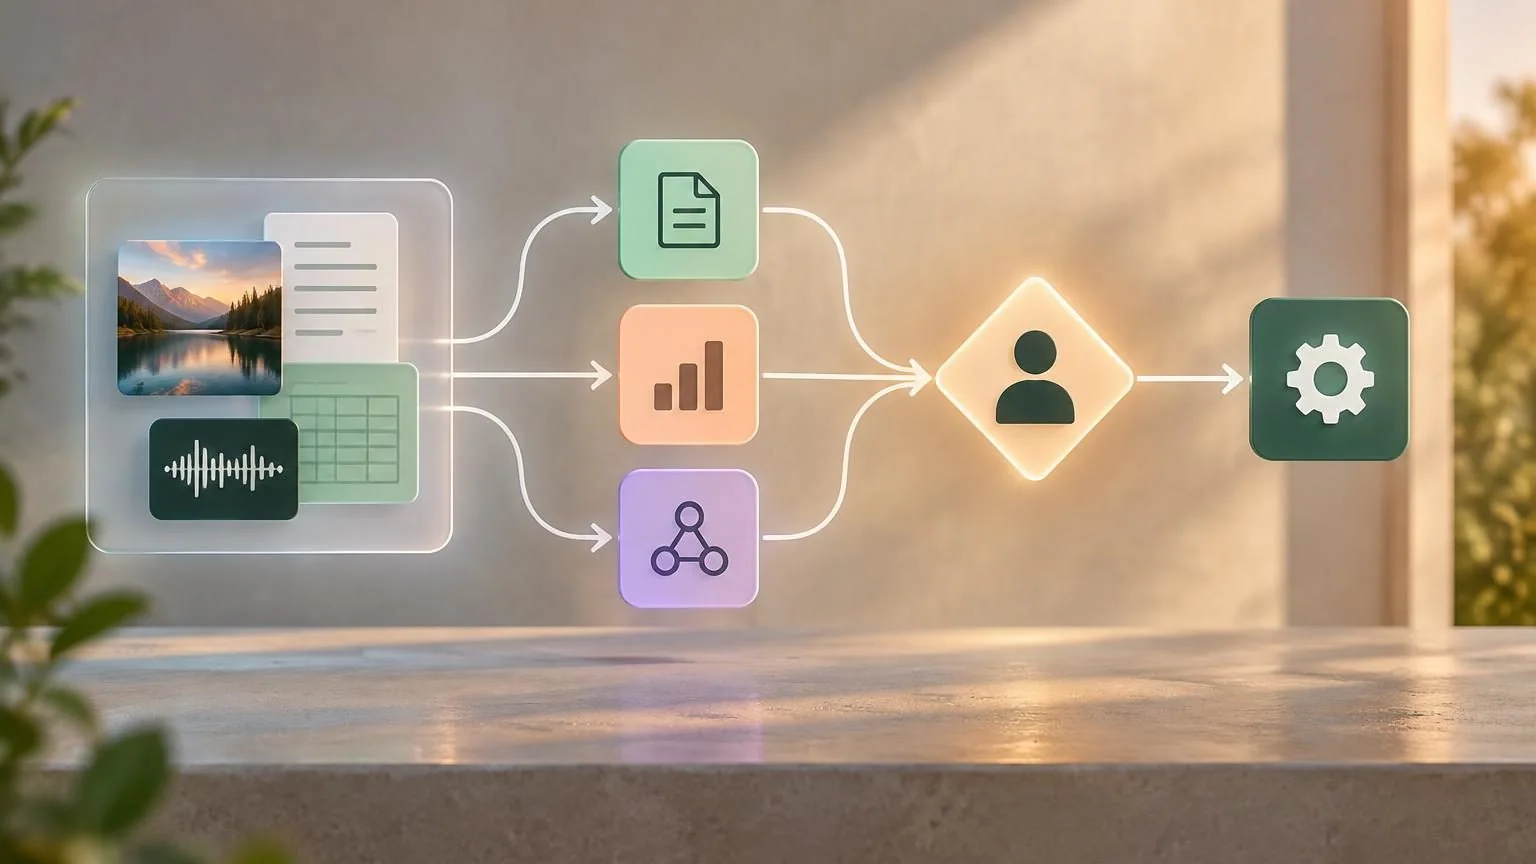
JSON and images change how evidence is supplied
Requests go to POST /v1/decisions; gpt-6-luna is currently the only supported model. The reference accepts 1–400 questions about shared input. Each question can return a predicate, a choice from supplied options, or a score against ordered levels.
For structured evidence, place an input_json part’s object or array in its data field. Within message content, the guide limits that part to user messages. Individual questions can also carry their own reference images, rather than requiring every image to sit in shared evidence.
Our suggested applications: classify incoming tickets into a defined taxonomy; propose a department for an intake request; or evaluate a draft answer against a specific relevance rubric. Keep these as separate questions so a routing suggestion does not silently become permission to execute a customer-facing action.
Shared-input caching has an important boundary
Caching reuses a matching prefix of shared input across requests. The guide requires at least 1,024 tokens in that reusable prefix; question instructions and question-specific images are outside it. Reuse therefore depends on identical shared evidence, not merely asking similar questions.
For a pilot, we recommend separating stable reference evidence from changing questions, then checking actual cache usage. Do not assume that adding images to each question will produce cache savings, or that a cache hit demonstrates better decision quality.
Where business automation should stop for review
The API returns typed answers; the application executes any selected actions. OpenAI recommends setting routing and review thresholds using labeled application examples and the costs of false positives and false negatives.
Our operational recommendation is to preserve an explicit approval boundary:
- Allow a pilot to suggest tags, queues or review priorities before enabling consequential actions.
- Send ambiguous, conflicting or insufficient evidence to a named human reviewer.
- Require authorized human approval before payments, account restrictions or decisions affecting access to essential services.
- Compare proposed routes with human labels and inspect errors by category before expanding scope.
For teams that tested the beta, the next step is a focused regression test of the new evidence formats and caching behavior—not automatic expansion of agent permissions. This release establishes new API capabilities; it is not evidence that a particular business workflow is accurate or ready for unattended deployment.