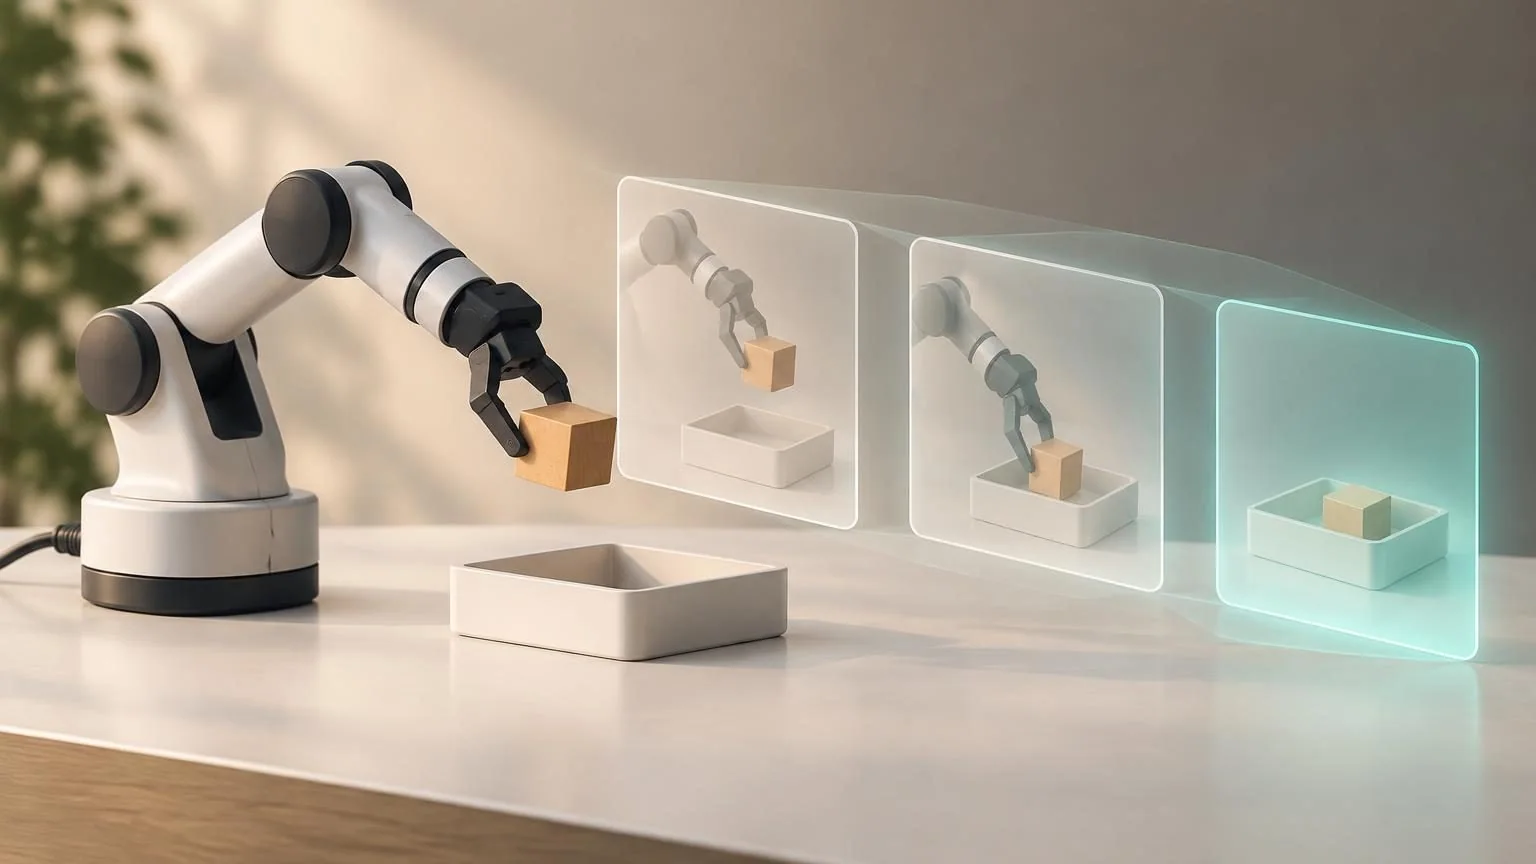
Alibaba DAMO Academy researchers submitted RynnUnify: Towards Unified Embodied Brain to arXiv on October 23, 2026. The work combines embodied understanding with video prediction, allowing a system to alternate between reasoning about a task and imagining its visual consequences. This is a research milestone, not the announcement of a generally available industrial robot service.
Planning with predicted scenes
The paper describes a 16-billion-parameter model for spatial reasoning, physical prediction and grounding. Its central idea is to connect understanding of a scene with anticipation of how that scene changes across successive subtasks. An agentic extension learns when generated visual evidence may help answer a question; a separate world-action extension connects predictive representations to robot control.
The accompanying repository explains the structure more concretely: an 8B autoregressive reasoner works with an 8B rectified-flow video generator. The reasoner proposes a subtask, visual description and duration, and the generator predicts a segment. Scene memory carries information across segments. This makes generated video part of the planning process, rather than simply an illustration added after a textual plan.
What the reported results measure
The authors introduce two evaluations, Rynn-VP for long-horizon visual planning and Rynn-GEU for anticipatory reasoning. They report a 9.75-point Rynn-VP improvement over Cosmos 3 Nano and a 6-point average gain from the agentic extension over direct reasoning on Rynn-GEU. These are author-reported comparisons on specified evaluations.
For control, the paper reports 51.5% success on 20 selected composite RoboCasa365 tasks and 46.7% average success across three real-robot tasks. Those denominators matter. Selected tasks and a small real-world evaluation do not establish reliable performance across a warehouse, a home or a manufacturing line. They identify a promising research direction with substantial remaining failure rates.
Why selective imagination matters
The repository describes reinforcement learning that teaches an agent to choose direct reasoning or generation-assisted reasoning. Its generator stays frozen during that training. The practical attraction is selective use: predicting a future scene could help with an occluded object or an interaction whose outcome is otherwise unclear, while straightforward questions may not need that extra work.
Our assessment is that the key question for this approach is whether the predicted scene supplies useful evidence or reinforces an incorrect assumption. A plausible-looking video can still put an object in the wrong place or omit a collision. In a deployment evaluation, predicted frames should therefore be compared with observed outcomes, including cases where the original interpretation was wrong.
The useful business question is recoverability
For an operator considering embodied automation, a useful trial would focus on a bounded manipulation task with known starting conditions. Measure task completion, physical interventions and whether the system recognizes when the environment differs from its prediction. Count recovery time as well as successful movements. These are proposed evaluation measures, not results from Nerova testing.
A robot that can plan a long sequence still needs a way to stop when an object slips, a person enters the work area or a tool fails. Control limits and independent emergency stopping remain separate from a model’s reasoning ability. The value of visual planning would be stronger if it reduced those interventions without making failures harder to detect.
The public repository supplies research workflows and checkpoint references, but its licensing notes distinguish project code from weights, datasets and figures, which have separate rights. Teams should inspect the relevant artifact terms rather than infer a universal license from the code repository. RynnUnify’s contribution is a testable connection between understanding, prediction and action; its operational reliability remains a question for further evidence.