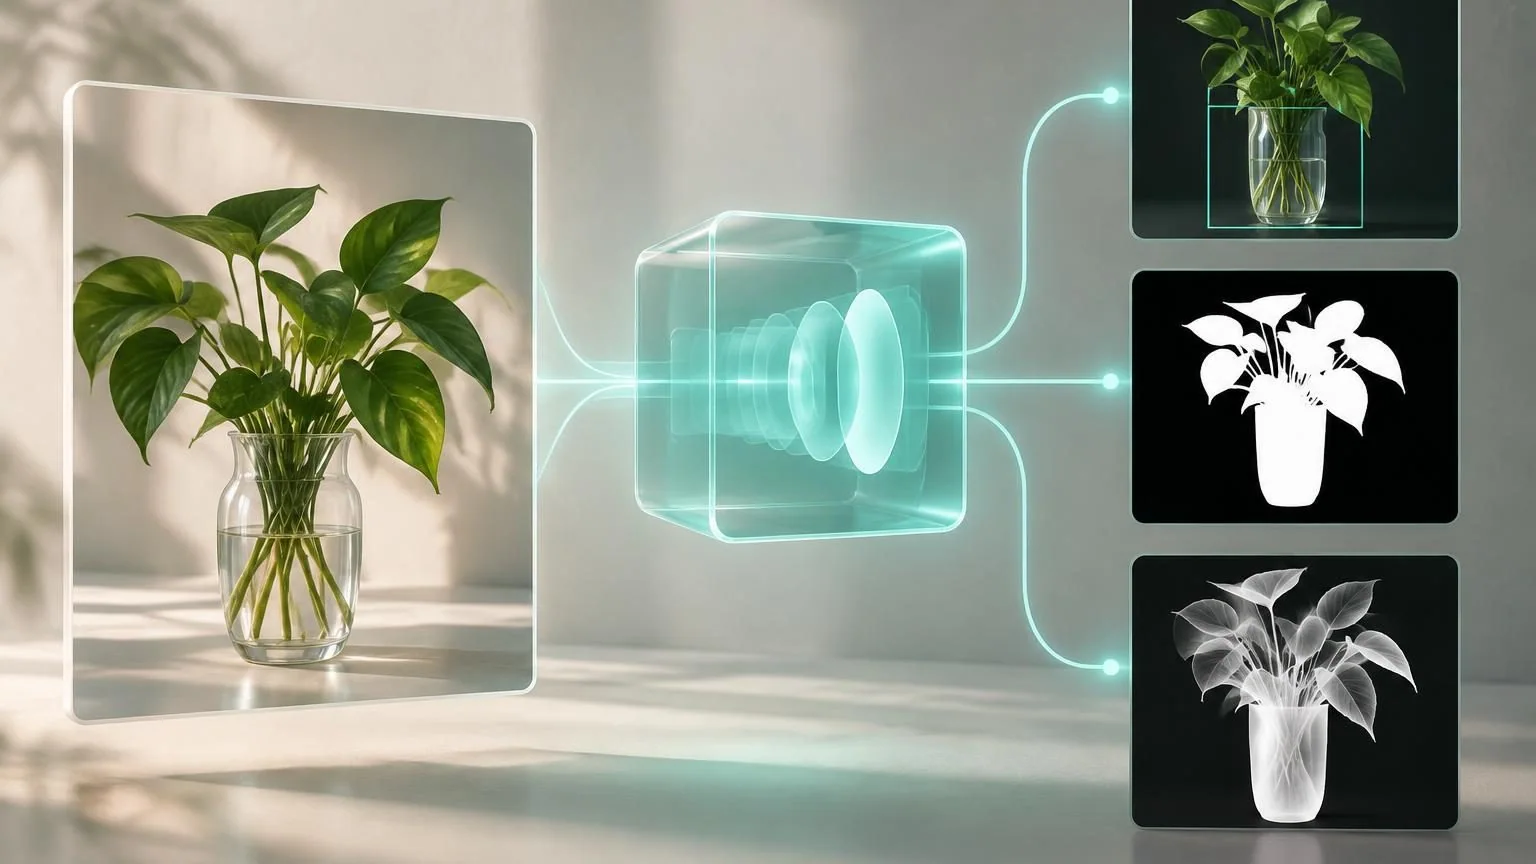
Tencent’s WeChat Vision team introduced WeVisOne-VL in a research report submitted on October 22, 2026, bringing object detection, counting, OCR, segmentation and matting into one vision-language system. The research record also shows a revision on October 24.
What is available, and what was actually announced?
The firm October 22 milestone is the report’s initial submission, not a separately verified production-service launch. Tencent’s repository announces an October release of both model sizes, an inference package and evaluation tooling, but its release notice specifies the month rather than an exact download-release day.
- Downloadable weights: As checked November 1, Tencent’s official repositories contain WeVisOne-VL-2B and WeVisOne-VL-4B model files. These are available artifacts, not merely promised future checkpoints.
- Preview or demo: Tencent links hosted demonstrations for both sizes. A demo permits exploration; it does not establish a managed production service or service-level commitment.
- API availability: The reviewed official materials do not announce a Tencent-hosted commercial API. Both Hugging Face pages state that no Inference Provider deploys the model. Self-hosting examples should not be mistaken for hosted API availability.
Why the pixel decoder changes the story
Built on Qwen3-VL, WeVisOne-VL connects structured coordinate predictions to a roughly 9.6-million-parameter pixel decoder. Tencent describes points, boxes, binary masks and continuous alpha mattes within the same architecture, without a separate SAM segmentation backbone at inference. Segmentation marks object membership; an alpha matte represents partial opacity, useful around fine edges.
The practical distinction is between finding a product and extracting a usable cutout. Our interpretation is that one perception interface could reduce handoffs between separate localization and editing components. That is an architectural opportunity, not evidence of lower production cost or better throughput: the project page establishes the combined outputs, not those business outcomes.
There is an important integration condition. The official 4B model card identifies mask_decoder.pt as a required core component, and its matting example uses Tencent’s inference package. A pilot should therefore verify that its actual serving path produces masks and mattes, rather than treating a successful text response as proof of full pixel-level support.
What the 2B and 4B results do—and do not—settle
Tencent’s published evaluation reports Dense200 detection F1 of 61.4 for 2B and 71.3 for 4B. But larger is not uniformly better: on P3M-500-NP box matting, reported error is 6.6 for 2B versus 7.3 for 4B, where lower is better. These are author-reported results under the repository’s evaluation protocol, not Nerova tests or a measured business-workflow advantage.
The operational implication is to compare the variants on the output that matters. A catalog workflow might prioritize cutout boundaries; a stock-photo review workflow might prioritize complete object counts. Benchmark leadership alone does not resolve that choice. Our recommendation follows from the task-dependent results, rather than assuming the 4B label guarantees superior outcomes everywhere.
The limits that should shape any business pilot
The 2B model card describes single-turn image perception, no explicit chain-of-thought output, and a pixel decoder that rejects video grids. It warns that alpha boundaries depend on resolution, occlusion, transparency and prompt wording. The stated intended use is research, excluding identification of individuals and autonomous high-impact decisions. This is not a demonstrated video-monitoring or autonomous decision product.
For a controlled evaluation, we would test missing-target images as well as present objects, compare both sizes on identical inputs, and inspect transparent edges manually. Record review effort and end-to-end processing time before expanding scope. Those are proposed acceptance checks, not tests we performed. They directly address the documented boundary sensitivities and the model’s designed ability to return None for an absent target.
As of November 1, the durable news is a downloadable unified-perception research release—not a verified managed API launch. Its promise is fewer perception handoffs; its unresolved business question is whether those combined outputs meet a particular workflow’s accuracy, latency and review requirements.